Semantic-Aware Contrasting with Explicitly Disentangled Representations for AI-Generated Video Detection
DOI:
https://doi.org/10.64509/jicn.24.159Keywords:
AI-Generated Video Detection, Representation Disentanglement Learning, Contrastive Learning, Video AnalysisAbstract
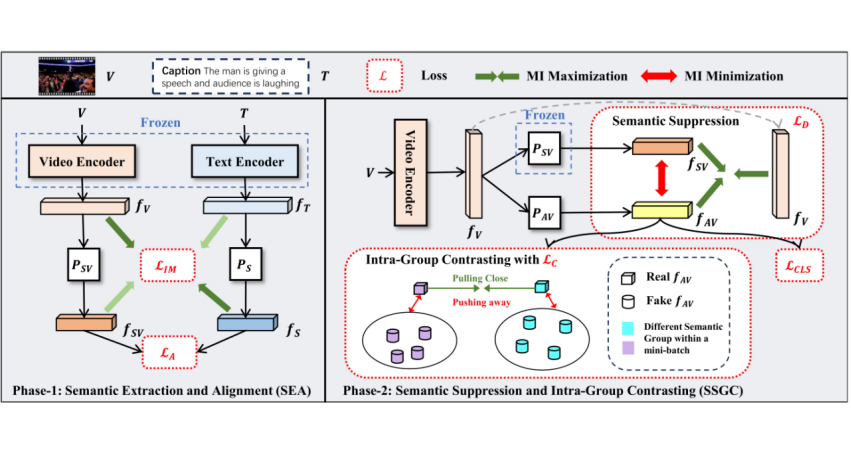
The rapid proliferation of AI-generated videos (AIGVs) has raised critical concerns about content authenticity and trustworthy media consumption, underscoring the need for robust AIGV detection. Despite recent progress, existing benchmarks suffer from a fundamental limitation: real and fake videos are often collected or generated from different semantic distributions. As a result, detectors may rely on spurious correlations involving objects, scenes, or actions rather than intrinsic artifacts introduced by generative models. This limitation calls for a benchmark that explicitly aligns real and generated videos at the semantic level, enabling detection methods to be evaluated and optimized under controlled content conditions. To this end, we introduce SAVGE, a large-scale semantically aligned AIGV detection dataset comprising 2,369,822 videos, including 424,115 real videos and 1,945,707 generated videos. SAVGE organizes samples into real--fake semantic groups by using captions paired with real videos as prompts for text-to-video generation, thereby providing both group-level correspondence and textual semantic anchors. Based on SAVGE, we further propose Explicit Disentangling and Semantic-aware Contrasting (EDSC), a model-agnostic training framework for learning artifact-focused representations with reduced semantic interference. EDSC first extracts and aligns visual semantic features with textual representations, and then explicitly suppresses semantic information in the artifact branch while contrasting real and fake samples within each semantic group. By integrating caption-guided semantic supervision with intra-group contrastive learning in a two-phase optimization strategy, EDSC encourages detectors to capture generation-related cues under matched semantic conditions. Extensive experiments on SAVGE and GenVideo demonstrate that EDSC improves most evaluated backbone--metric combinations, enhances robustness under challenging evaluation settings, and strengthens cross-dataset generalization. These results highlight the importance of semantic alignment in AIGV detection and validate explicit semantic--artifact disentanglement as an effective strategy for robust detector learning.
Downloads
References
[1] Wang, S., Liu, J., Wang, W., Jin, Y., Du, J., Han, Z.: MMGT: Motion Mask Guided Two-Stage Network for Co-Speech Gesture Video Generation. IEEE Transactions on Circuits and Systems for Video Technology 36(2), 1446–1459 (2026) https://doi.org/10.1109/TCSVT.2025.3604109
[2] Wang, C., Hu, P., Zhao, H., Guo, Y., Gu, J., Dong, X., Han, J., Xu, H., Liang, X.: Uniadapter: All-in-one control for flexible video generation. IEEE Transactions on Circuits and Systems for Video Technology 35(6), 6059–6073 (2025) https://doi.org/10.1109/TCSVT.2025.3532495
[3] Ho, J., Chan, W., Saharia, C., Whang, J., Gao, R., Gritsenko, A., Kingma, D.P., Poole, B., Norouzi, M., Fleet, D.J., et al.: Imagen video: High definition video generation with diffusion models. arXiv preprint arXiv:2210.02303 (2022) https://doi.org/10.48550/arXiv.2210.02303
[4] Ni, H., Shi, C., Li, K., Huang, S.X., Min, M.R.: Conditional image-to-video generation with latent flow diffusion models. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 18444–18455 (2023)
[5] Jiang, Y., Wu, T., Yang, S., Si, C., Lin, D., Qiao, Y., Loy, C.C., Liu, Z.: Videobooth: Diffusion-based video generation with image prompts. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 6689–6700 (2024). https://doi.org/10.1109/CVPR52733.2024.00639
[6] Wang, J., Yuan, H., Chen, D., Zhang, Y., Wang, X., Zhang, S.: ModelScope text-to-video technical report. arXiv preprint arXiv:2308.06571 (2023) https://doi.org/10.48550/arXiv.2308.06571
[7] Yang, Y., Yue, G., Zhou, W., Mao, X., Wang, R., Zhao, B.: Expressive Human Volumetric Video Generation With Rich Text. IEEE Transactions on Circuits and Systems for Video Technology 36(4), 5424–5436 (2026) https://doi.org/10.1109/TCSVT.2025.3628996
[8] Wang, C., Yan, S., Chen, Y., Wang, X., Wang, Y., Dong, M., Yang, X., Li, D., Zhu, R., Clifton, D.A.: Denoising Reuse: Exploiting Inter-Frame Motion Consistency for Efficient Video Generation. IEEE Transactions on Circuits and Systems for Video Technology 35(9), 8436–8451 (2025) https://doi.org/10.1109/TCSVT.2025.3548728
[9] Yan, Z., Zhang, Y., Fan, Y., Wu, B.: UCF: Uncovering Common Features for Generalizable Deepfake Detection. In 2023 IEEE/CVF International Conference on Computer Vision (ICCV), pp. 22355–22366 (2023). https://doi.org/10.1109/ICCV51070.2023.02048
[10] Chen, H., Hong, Y., Huang, Z., Xu, Z., Gu, Z., Li, Y., Lan, J., Zhu, H., Zhang, J., Wang, W., Li, H.: DeMamba: AI-Generated Video Detection on Million-Scale GenVideo Benchmark. arXiv preprint arXiv:2405.19707 (2024) https://doi.org/10.48550/arXiv.2405.19707
[11] Rössler, A., Cozzolino, D., Verdoliva, L., Riess, C., Thies, J., Nießner, M.: FaceForensics++: Learning to Detect Manipulated Facial Images. In 2019 IEEE/CVF International Conference on Computer Vision, ICCV, pp. 1–11 (2019). https://doi.org/10.1109/ICCV.2019.00009
[12] Dong, J., Wang, W., Tan, T.: CASIA Image Tampering Detection Evaluation Database. In 2013 IEEE China Summit and International Conference on Signal and Information Processing, ChinaSIP, pp. 422–426 (2013). https://doi.org/10.1109/ChinaSIP.2013.6625374
[13] Saito, M., Matsumoto, E., Saito, S.: Temporal generative adversarial nets with singular value clipping. In Proceedings of the IEEE International Conference on Computer Vision, pp. 2849–2858 (2017). https://doi.org/10.1109/ICCV.2017.308
[14] Tulyakov, S., Liu, M.-Y., Yang, X., Kautz, J.: Mocogan: Decomposing motion and content for video generation. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pp. 1526–1535 (2018). https://doi.org/10.1109/CVPR.2018.00165
[15] Li, Y., Gan, Z., Shen, Y., Liu, J., Cheng, Y., Wu, Y., Carin, L., Carlson, D., Gao, J.: StoryGAN: A Sequential Conditional GAN for Story Visualization. In 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), pp. 6322–6331 (2019). https://doi.org/10.1109/CVPR.2019.00649
[16] Luo, Z., Chen, D., Zhang, Y., Huang, Y., Wang, L., Shen, Y., Zhao, D., Zhou, J., Tan, T.: Notice of Removal: VideoFusion: Decomposed Diffusion Models for High-Quality Video Generation. In 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), pp. 10209–10218 (2023). https://doi.org/10.1109/CVPR52729.2023.00984
[17] Ma, X., Wang, Y., Jia, G., Chen, X., Liu, Z., Li, Y.-F., Chen, C., Qiao, Y.: Latte: Latent diffusion transformer for video generation. arXiv preprint arXiv:2401.03048 (2024) https://doi.org/10.48550/arXiv.2401.03048
[18] Zheng, Z., Peng, X., Yang, T., Shen, C., Li, S., Liu, H., Zhou, Y., Li, T., You, Y.: Open-Sora: Democratizing Efficient Video Production for All. arXiv preprint arXiv:2412.20404 (2024) https://doi.org/10.48550/arXiv.2412.20404
[19] Wang, S.-Y., Wang, O., Zhang, R., Owens, A., Efros, A.A.: CNN-Generated Images Are Surprisingly Easy to Spot… for Now. In 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), pp. 8692–8701 (2020). https://doi.org/10.1109/CVPR42600.2020.00872
[20] Durall, R., Keuper, M., Keuper, J.: Watch Your UpConvolution: CNN Based Generative Deep Neural Networks Are Failing to Reproduce Spectral Distributions. In 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), pp. 7887–7896 (2020). https://doi.org/10.1109/CVPR42600.2020.00791
[21] Li, Y., Chang, M.-C., Lyu, S.: In Ictu Oculi: Exposing AI Created Fake Videos by Detecting Eye Blinking. In 2018 IEEE International Workshop on Information Forensics and Security (WIFS), pp. 1–7 (2018). https://doi.org/10.1109/WIFS.2018.8630787
[22] Bertasius, G., Wang, H., Torresani, L.: Is space-time attention all you need for video understanding? In Proceedings of International Conference on Machine Learning, pp. 813–824 (2021)
[23] Frank, J., Eisenhofer, T., Schönherr, L., Fischer, A., Kolossa, D., Holz, T.: Leveraging Frequency Analysis for Deep Fake Image Recognition. In Proceedings of the 37th International Conference on Machine Learning, pp. 3247–3258 (2020)
[24] Zhu, M., Chen, H., Yan, Q., Huang, X., Lin, G., Li, W., Tu, Z., Hu, H., Hu, J., Wang, Y.: Genimage: A million-scale benchmark for detecting ai-generated image. In Proceedings of the 37th International Conference on Neural Information Processing Systems, pp. 77771–77782 (2023)
[25] Ojha, U., Li, Y., Lee, Y.J.: Towards Universal Fake Image Detectors that Generalize Across Generative Models. In 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), pp. 24480–24489 (2023). https://doi.org/10.1109/CVPR.2023.02345
[26] Zhang, J., Jian, L., Ma, Z., Ma, J., Huang, X.: Forgery Localization Via Extracting Generic Features and Multiple Prior Fusion. Journal of Intelligent Computing and Networking 2(2), 1–13 (2026) https://doi.org/10.64509/jicn.22.94
[27] Li, Y., Yang, X., Sun, P., Qi, H., Lyu, S.: Celeb-DF: A Large-Scale Challenging Dataset for DeepFake Forensics. In 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), pp. 3204–3213 (2020). https://doi.org/10.1109/CVPR42600.2020.00327
[28] Dolhansky, B., Bitton, J., Pflaum, B., Lu, J., Howes, R., Wang, M., Ferrer, C.C.: The DeepFake Detection Challenge (DFDC) Dataset. In arXiv Preprint arXiv:2006.07397 (2020). https://doi.org/10.48550/arXiv.2006.07397
[29] Ni, Z., Yan, Q., Huang, M., Yuan, T., Tang, Y., Hu, H., Chen, X., Wang, Y.: GenVidBench: A 6-Million Benchmark for AI-Generated Video Detection. Proceedings of the Fortieth AAAI Conference on Artificial Intelligence and Thirty-Eighth Conference on Innovative Applications of Artificial Intelligence and Sixteenth Symposium on Educational Advances in Artificial Intelligence, 15582–15590 (2026) https://doi.org/10.1609/aaai.v40i18.38587
[30] Chen, W., Zheng, W., Zheng, Y., Chen, L., Zhou, J., Lu, J., Duan, Y.: GenWorld: Towards Detecting AI-generated Real-world Simulation Videos. arXiv preprint arXiv:2506.10975 (2025) https://doi.org/10.48550/arXiv.2506.10975
[31] Jiang, C., Dong, W., Zhang, Z., Yu, F., Peng, W., Yuan, X., Bi, Y., Zhao, M., Zhou, Z., Si, C., et al.: Ivy-Fake: A Unified Explainable Framework and Benchmark for Image and Video AIGC Detection. In Proceedings of the 2026 International Conference on Multimedia Retrieval, pp. 2438–2447 (2026). https://doi.org/10.1145/3805622.3810615
[32] Zheng, C., Suo, R., Lin, C., Zhao, Z., Yang, L., Liu, S., Yang, M., Wang, C., Shen, C.: D3: Training-Free AI-Generated Video Detection Using Second-Order Features. In Proceedings of the IEEE/CVF International Conference on Computer Vision, pp. 12852–12862 (2025). https://doi.org/10.1109/ICCV.2025.01194
[33] Chen, H., Sun, J., Liu, Y., Shi, H., Hu, D.: Self-Supervised Disentangled Representation Learning via Compositional Invariance. IEEE Transactions on Circuits and Systems for Video Technology 36(3), 3201–3214 (2026) https://doi.org/10.1109/TCSVT.2025.3625076
[34] Dang, Z., Luo, M., Jia, C., Dai, G., Wang, J., Chang, X., Wang, J.: Disentangled Representation Learning With Transmitted Information Bottleneck. IEEE Transactions on Circuits and Systems for Video Technology 34(12), 13297–13310 (2024) https://doi.org/10.1109/TCSVT.2024.3443122
[35] Yu, M., Li, H., Yang, J., Li, X., Li, S., Zhang, J.: FDML: Feature disentangling and multi-view learning for face forgery detection. Neurocomputing 572, 127192 (2024) https://doi.org/10.1016/j.neucom.2023.127192
[36] Xu, H., Ye, Q., Wu, X., Yan, M., Miao, Y., Ye, J., Xu, G., Hu, A., Shi, Y., Xu, G., Li, C., Qian, Q., Que, M., Zhang, J., Zeng, X., Huang, F.: Youku-mPLUG: A 10 Million Large-scale Chinese Video-Language Dataset for Pre-training and Benchmarks. arXiv preprint arXiv:2306.04362 (2023) https://doi.org/10.48550/arXiv.2306.04362
[37] Krishna, R., Hata, K., Ren, F., Fei-Fei, L., Niebles, J.C.: Dense-captioning events in videos. In Proceedings of the IEEE International Conference on Computer Vision, pp. 706–715 (2017). https://doi.org/10.1109/ICCV.2017.83
[38] Goyal, R., Ebrahimi Kahou, S., Michalski, V., Materzynska, J., Westphal, S., Kim, H., Haenel, V., Fruend, I., Yianilos, P., Mueller-Freitag, M., et al.: The “something something” video database for learning and evaluating visual common sense. In Proceedings of the IEEE International Conference on Computer Vision, pp. 5842–5850 (2017). https://doi.org/10.1109/ICCV.2017.622
[39] cerspense: ZeroScope-v2-576w. Hugging Face (2023). https://huggingface.co/cerspense/zeroscope_v2_576w
[40] Chen, H., Xia, M., He, Y., Zhang, Y., Cun, X., Yang, S., Xing, J., Liu, Y., Chen, Q., Wang, X., et al.: Videocrafter1: Open diffusion models for high-quality video generation. arXiv preprint arXiv:2310.19512 (2023) https://doi.org/10.48550/arXiv.2310.19512
[41] Wan, T., Wang, A., Ai, B., Wen, B., Mao, C., Xie, C.-W., Chen, D., Yu, F., Zhao, H., Yang, J., et al.: Wan: Open and Advanced Large-Scale Video Generative Models. arXiv preprint arXiv:2503.20314 (2025) https://doi.org/10.48550/arXiv.2503.20314
[42] Zhang, Y., Xing, Z., Zeng, Y., Fang, Y., Chen, K.: PIA: Your Personalized Image Animator via Plug-andPlay Modules in Text-to-Image Models. arXiv preprint arXiv:2312.13964 (2023) https://doi.org/10.48550/arXiv.2312.13964
[43] Morph studio. https://www.morphstudio.com/ Accessed 2026-09-18
[44] Zhang, D.J., Wu, J.Z., Liu, J.-W., Zhao, R., Ran, L., Gu, Y., Gao, D., Shou, M.Z.: Show-1: Marrying pixel and latent diffusion models for text-to-video generation. International Journal of Computer Vision 133, 1879–1893 (2025) https://doi.org/10.1007/s11263-024-02271-9
[45] Runway Research: Gen-2: Generate Novel Videos with Text, Images or Video Clips. https://research.runwayml.com/gen2 Accessed 2026-09-18
[46] Wang, Y., Chen, X., Ma, X., Zhou, S., Huang, Z., Wang, Y., Yang, C., He, Y., Wang, Y., Yang, P., et al.: Lavie: High-quality video generation with cascaded latent diffusion models. arXiv preprint arXiv:2309.15103 (2023) https://doi.org/10.48550/arXiv.2309.15103
[47] Wang, L., Huang, B., Zhao, Z., Tong, Z., He, Y., Wang, Y., Wang, Y., Qiao, Y.: VideoMAE V2: Scaling video masked autoencoders with dual masking. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 14549–14560 (2023). https://doi.org/10.1109/CVPR52729.2023.01398
[48] Ni, B., Peng, H., Chen, M., Zhang, S., Meng, G., Fu, J., Xiang, S., Ling, H.: Expanding language-image pretrained models for general video recognition. In Proceedings of European Conference on Computer Vision, pp. 1–18 (2022). https://doi.org/10.1007/978-3-031-19772-7_1
[49] Devlin, J., Chang, M.-W., Lee, K., Toutanova, K.: BERT: Pre-training of deep bidirectional transformers for language understanding. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, pp. 4171–4186 (2019). https://doi.org/10.18653/v1/N19-1423
[50] Hjelm, R.D., Fedorov, A., Lavoie-Marchildon, S., Grewal, K., Bachman, P., Trischler, A., Bengio, Y.: Learning deep representations by mutual information estimation and maximization. In Proceedings of 7th International Conference on Learning Representations, ICLR (2019)
[51] Nowozin, S., Cseke, B., Tomioka, R.: f-GAN: training generative neural samplers using variational divergence minimization. In Proceedings of the 30th International Conference on Neural Information Processing Systems, pp. 271–279 (2016)
[52] Oord, A.v.d., Li, Y., Vinyals, O.: Representation learning with contrastive predictive coding. arXiv preprint arXiv:1807.03748 (2018) https://doi.org/10.48550/arXiv.1807.03748
[53] Qian, Y., Yin, G., Sheng, L., Chen, Z., Shao, J.: Thinking in frequency: Face forgery detection by mining frequency-aware clues. In Proceedings of European Conference on Computer Vision, pp. 86–103 (2020). https://doi.org/10.1007/978-3-030-58610-2_6
[54] Tan, C., Zhao, Y., Wei, S., Gu, G., Liu, P., Wei, Y.: Rethinking the up-sampling operations in cnn-based generative network for generalizable deepfake detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 28130–28139 (2024). https://doi.org/10.1109/CVPR52733.2024.02657
[55] Radford, A., Kim, J.W., Hallacy, C., Goh, G., Agarwal, S., Sastry, G., Askell, A., Mishkin, P., Clark, J.: Learning transferable visual models from natural language supervision. In Proceedings of International Conference on Machine Learning, pp. 8748–8763 (2021)
[56] Xu, Y., Liang, J., Jia, G., Yang, Z., Zhang, Y., He, R.: Tall: Thumbnail layout for deepfake video detection. In Proceedings of the IEEE/CVF International Conference on Computer Vision, pp. 22658–22668 (2023). https://doi.org/10.1109/ICCV.2023.02071
[57] Hu, X., Qian, Y., Yu, J., Liu, J., Ji, X., Tang, P., Xu, C., Liu, J., et al.: The Landscape of Medical Agents: A Survey. TechRxiv (2026) https://doi.org/10.36227/techrxiv.176581395.56964766/v4
[58] Qian, Y., Hu, X., Yu, J., Xin, S., Chen, X., Zhang, J., Jiang, P.-T., Liu, J., Li, H.B.: MedMASLab: A Unified Orchestration Framework for Benchmarking Multimodal Medical Multi-Agent Systems. arXiv preprint arXiv:2603.09909 (2026) https://doi.org/10.48550/arXiv.2603.09909
[59] Qian, Y., Yu, J., Liu, J., Wang, M., Li, H.B., Hu, X.: Med-OPD: Improving Medical Vision-Language Models via Evidence-Aware On-Policy Distillation. arXiv preprint arXiv:2607.16303 (2026) https://doi.org/10.48550/arXiv.2607.16303
Downloads
Published
Issue
Section
License
Copyright (c) 2026 Authors

This work is licensed under a Creative Commons Attribution 4.0 International License.
How to Cite